

Vulsar AI’s new benchmark compares the capabilities of 24 language models to humans’ ability to write long text. 475 tasks were used for testing, and the results were evaluated using a special model trained on human preferences.
The leader among AIs is GPT 6 Astra, with a predicted winning probability of 87.8%. This is slightly higher than the result of popular amateur writers – 86.6%. However, when compared separately to professional authors, it turns out that this gap works in people’s favor. GPT 5.6 Sol achieved 77.6% and Claude Fable 5.1 achieved 70.3%.
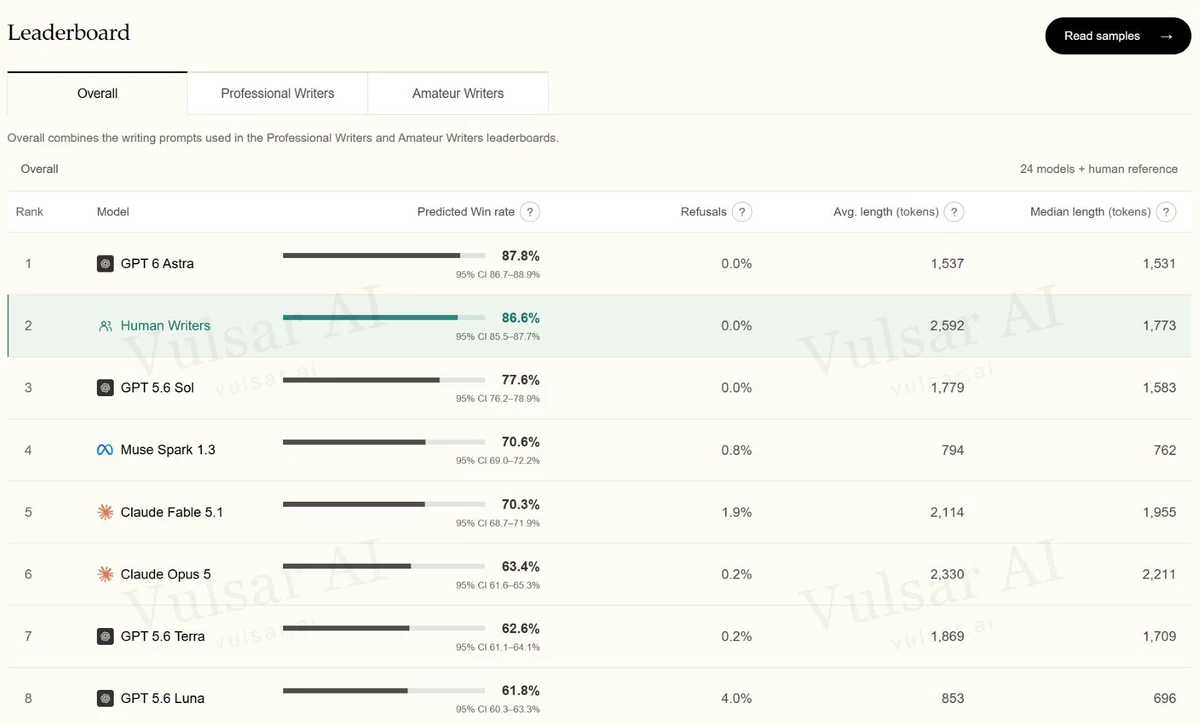
Performance is significantly lower for smaller models. Claude Opus 5, Kimi K3 and Grok 4.6 scored about 50 to 65%, while Qwen3.8-27B scored 23.2%, DeepSeek V4.1 Flash scored 19.8%, and Gemma 4 26B scored only 10.9%.
Interestingly, people created the longest response on average – about 2592 tokens, compared to 1537 for GPT 6 Astra. The test authors note that for complex tasks, small models often lose coherence and start to repeat themselves.